
Intelligence no single company controls.
An open network of AI providers, a router that picks one for you without reading your prompt, and memory that stays on your device. Anyone with a GPU can supply intelligence and earn PAI for it.
Use it. Supply it. Own your context.
Today, one company holds the model, your conversations and the bill. Here each of those is held by a different party, and no single party can see or stop the whole.
Chat, or change one URL
Sign in with email or a wallet and chat. Developers keep the Anthropic, OpenAI or Gemini SDK they already use and point it at the network.
- Crypto top-ups (opening soon)
- Use your own vendor keys too
- Console with keys, limits and usage
Put a GPU to work for the network
Run one container next to an open-weight model. The router sends it signed traffic, checks its answers with canaries, and credits PAI reward points for verified work (off-chain today, with no cash value).
- Ollama, vLLM, llama.cpp, LM Studio
- No static IP or port forwarding
- Higher reasoning levels earn more
Your memory stays with you
Conversations and preferences live in your browser or the dsi harness on your machine. Providers see one request at a time, without your account identity. Text you type is sent as written unless you route through Synapse, which strips what identifies you.
- A different provider per session
- No per-query inspection by the router
- Little to leak: a provider holds one request, not your history
The cheapest provider that is good enough, chosen without reading your prompt.
The router sees the shape of a request — its length, the tools it needs, the reasoning level you ask for — never its meaning. It filters out every provider that can't handle the request, then balances cost, speed and quality among the rest.
If a provider disappears mid-answer, the stream continues on another one from the exact point it stopped. Your app sees one uninterrupted reply.
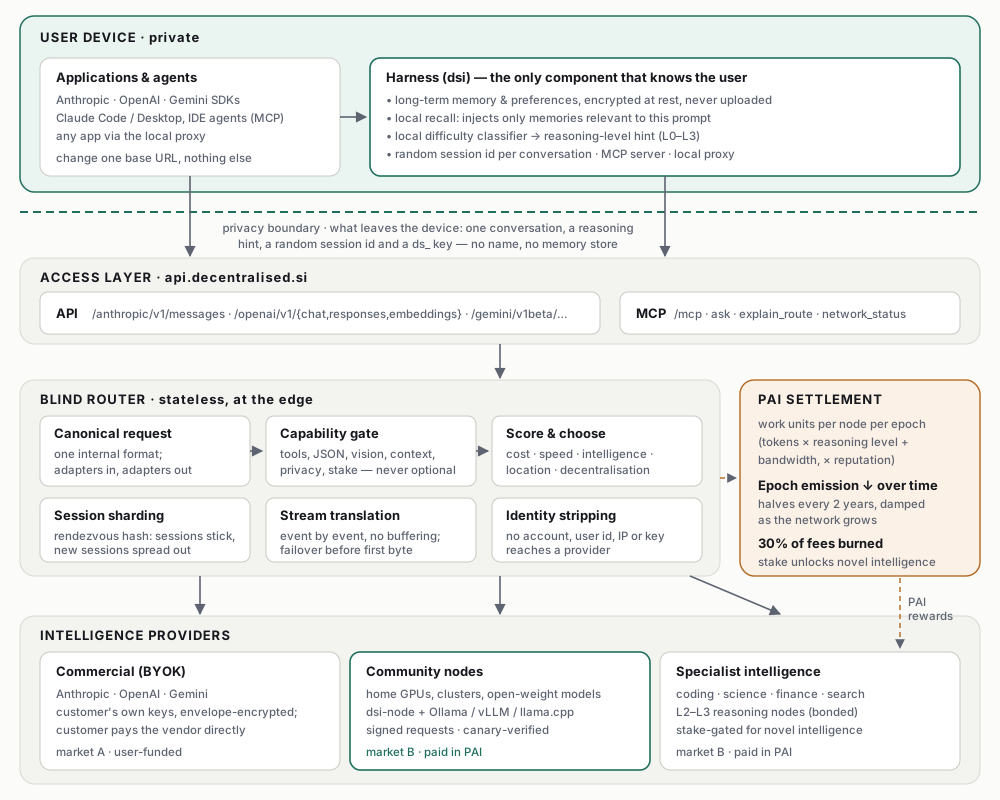
Reasoning levels
Every request is served at a level. Everyday answers are common knowledge and get cheaper every day. Frontier reasoning is scarce, so it needs a PAI stake. Stake is locked, not spent.
| Level | What it does | Knowledge | Reward | Stake to use (staking not open yet) | Nodes live |
|---|---|---|---|---|---|
| L0 · recall | Lookup, rewrite, classify (≤ 8B models) | common | ×1 | none | — |
| L1 · general | Everyday Q&A, summaries, code help (8–70B) | common | ×2 | none | — |
| L2 · reasoning | Multi-step analysis, agents (70B+, reasoning models) | novel | ×4 | from 1,000 PAI | — |
| L3 · frontier | Frontier-class and long-thinking models | novel | ×8 | from 10,000 PAI | — |
No single company holds your conversation, so none can lose it, read it, or switch it off.
| A centralised AI service | Decentralised.ai | |
|---|---|---|
| Where your history lives | On the vendor's servers | On your device; sent only with each request |
| Who sees who you are | The vendor, on every request | The router strips identity; providers see an anonymous request |
| Who reads your prompts to route them | The vendor | No one; routing uses structure and your own hints |
| What one provider sees | Everything, forever | One session, then a different provider for the next |
| When the provider goes down | You wait | The reply continues on another provider mid-stream |
| Who can switch you off | One company | No single operator; any node can serve |
Honest limits: a provider serving a request can read that request, as with any hosted model. The network limits how much any one of them sees and removes your identity from it. Confidential-computing nodes and anonymous relays are on the roadmap.
A capped token whose supply follows real usage.
PAI pays the people who supply intelligence. 500M of it can only ever be created by doing verified work, and every fee paid in PAI burns some of it.
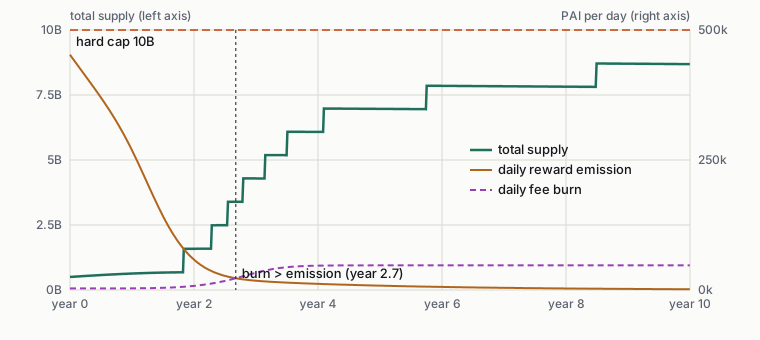
Common knowledge gets cheaper
As more operators serve L0–L1 models, the price of everyday answers falls every day. That's the live multiplier in the strip above.
Novel intelligence needs stake
L2 and L3 on the network require staked PAI, and the required stake rises with demand. That rations scarce reasoning by commitment, not by who you are. Your own vendor keys are never stake-gated.
Operators put skin in the game
Higher-level providers post a bond. Serving a cheaper model than declared costs half of it.
PAI currently runs on an off-chain ledger. The reference contract is unaudited and not deployed, and no token generation event is scheduled. Nothing on this page is an offer of securities or a promise of earnings; figures in the whitepaper are illustrative.
Three commands from GPU to paid node.
Docker Compose starts an open model server, a Cloudflare tunnel and dsi-node. The node registers its models, accepts only router-signed requests and heartbeats every 30 seconds. Rewards settle daily.
# Ollama + tunnel + dsi-node
curl -fsSLO https://decentralised.ai/dl/docker-compose.yml
# any open-weight model your hardware fits (see /node)
DSI_API_KEY=ds_live_... DSI_MODEL=qwen2.5:7b docker compose up -d

# already running vLLM / llama.cpp / LM Studio?
LLM_BASE_URL=http://localhost:8000/v1 node dsi-node.mjs up
node dsi-node.mjs earnings
Your SDK already works.
Drop-in Anthropic, OpenAI and Gemini APIs with streaming, tools, vision, files and batches, plus an MCP server. Use model: "auto" to let the router choose, or name a model to pin it.
from anthropic import Anthropic

client = Anthropic(
    api_key="ds_live_...",
    base_url="https://api.decentralised.ai/anthropic",
)
msg = client.messages.create(
    model="auto", max_tokens=1024,
    messages=[{"role": "user", "content": "Hello"}],
)
import Anthropic from "@anthropic-ai/sdk";

const client = new Anthropic({
  apiKey: process.env.DSI_API_KEY,
  baseURL: "https://api.decentralised.ai/anthropic",
});
from openai import OpenAI

client = OpenAI(
    api_key="ds_live_...",
    base_url="https://api.decentralised.ai/openai/v1",
)
client.chat.completions.create(model="auto", messages=[...])
# memory and preferences on your machine (Node 20+)
curl -fsSL https://decentralised.ai/dl/dsi.mjs -o ~/.local/bin/dsi
chmod +x ~/.local/bin/dsi
dsi login ds_live_...
dsi remember "I prefer concise answers with code first"
dsi chat
claude mcp add dsi -- dsi mcp   # same memory in Claude Code
Intelligence should be a public utility, not a private possession.
Start with a conversation, a line of code, or a spare GPU.